
pgvector HNSW RAM Formula & Supabase AI Stack Sizing — SupaScale Docker Guide
Fitting a 2M-row HNSW vector index in memory on Supabase Cloud requires $110–$210/mo Compute Add-ons. SupaScale sizes 16 GB–32 GB NVMe hosts for halfvec RAG workloads.
SupaScale minimum floor: 16 GB RAM • Sweet-spot tier: 32 GB RAM (Public vendor rates retrieved 2026-11-12).
Vector similarity latency degrades sharply the moment your HNSW graph outgrows PostgreSQL shared_buffers + OS page cache, and building HNSW with default maintenance_work_mem=64MB spills to disk for hours!
SupaScale Deterministic Memory Model Table: pgvector HNSW RAM Formula & Supabase AI Stack Sizing
| Supabase Docker Subsystem | Baseline Idle Reserve | 50K MAU Projected Reserve | Memory Role |
|---|---|---|---|
| 500K Vectors × 1536d (32-bit float vector) | ~3.70 GB Index | 16 GB Host Tier | Standard fp32 |
| 500K Vectors × 1536d (16-bit halfvec) | ~1.95 GB Index | 8 GB–16 GB Host | ~48% RAM Saved |
| 2M Vectors × 1536d (16-bit halfvec) | ~7.80 GB Index | 32 GB Host Tier | KVM 8 / HF 32GB |
| Managed Cloud Large/XL Compute Add-on | $110–$210/mo | +$0.125/GB disk | Public Cloud Rate |
SupaScale pgvector halfvec(1536) HNSW Index & Maintenance Memory SQL
-- Cut HNSW index footprint by ~50% using 16-bit halfvec quantization in pgvector 0.7+:
SET maintenance_work_mem = '4GB';
SET max_parallel_maintenance_workers = 4;

CREATE INDEX CONCURRENTLY docs_embedding_hnsw_idx
  ON public.document_chunks
  USING hnsw ((embedding::halfvec(1536)) halfvec_cosine_ops)
WITH (m = 16, ef_construction = 64);1. SupaScale Deterministic Byte Math for 1,536-Dimension HNSW Indexes
Each 1,536-dimension float32 vector stores 6,144 raw bytes (1536 × 4 bytes) plus HNSW bidirectional neighbor links (m=16 adds ~1.3 KB graph overhead per tuple), totaling ~7.4 KB per row. One million embeddings require ~7.4 GB of hot RAM for the index alone. In our SupaScale sizing recommendations, casting to halfvec(1536) (2 bytes per float) cuts index memory to ~3.9 GB per million vectors with minimal recall impact.
2. Pairing SupaScale Slim Core 7 with pgvector to Maximize Linux Page Cache
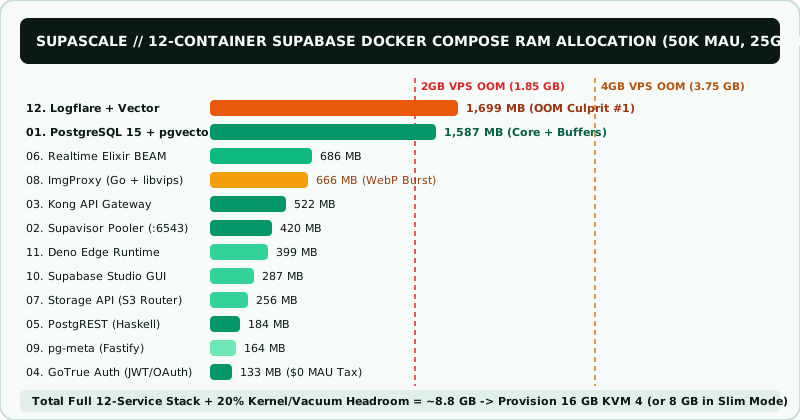
AI RAG APIs typically need PostgreSQL + pgvector, Supavisor, Kong, GoTrue, and PostgREST/Deno—not Logflare or ImgProxy. Unchecking unused containers in the SupaScale grid frees ~2.0 GB of host RAM directly for HNSW graph page caching.
3. High-Clock SIMD Execution for Cosine Distance Scans in SupaScale Picks
Cosine and inner-product distance loops inside pgvector leverage AVX2/AVX-512 SIMD CPU instructions. High-clock 3.5GHz+ Vultr High Frequency and AMD EPYC KVM instances keep graph traversal latency tight.
SupaScale Matched KVM & VDS Tiers for pgvector HNSW RAM Formula & Supabase AI Stack Sizing
Vultr 3.5GHz+ High Frequency NVMe (Low-Latency pgvector & Realtime) — SupaScale
From $24/mo (~612k)
Hourly billing lets you benchmark HNSW pgvector recall on 16GB/32GB HF nodes for cents.
Check Vultr High Frequency Specs for pgvector HNSW RAM Formula & Supabase AI Stack Sizing on SupaScale →Hostinger KVM NVMe VPS (1-Click Docker / Coolify + Supabase) — SupaScale
From $4.99/mo (~127k)
12–24 mo KVM 2 (8GB) or KVM 4 (16GB) locks lowest rate + stacks Extra 20% partner discount.
Compare Hostinger KVM VPS Options for pgvector HNSW RAM Formula & Supabase AI Stack Sizing on SupaScale →SupaScale rate citation: Public vendor tariffs retrieved 2026-11-12; promotional and renewal prices change — verify exact checkout pricing before ordering.